Google Expands TPU Chipset Lineup With New Systems for AI Agents
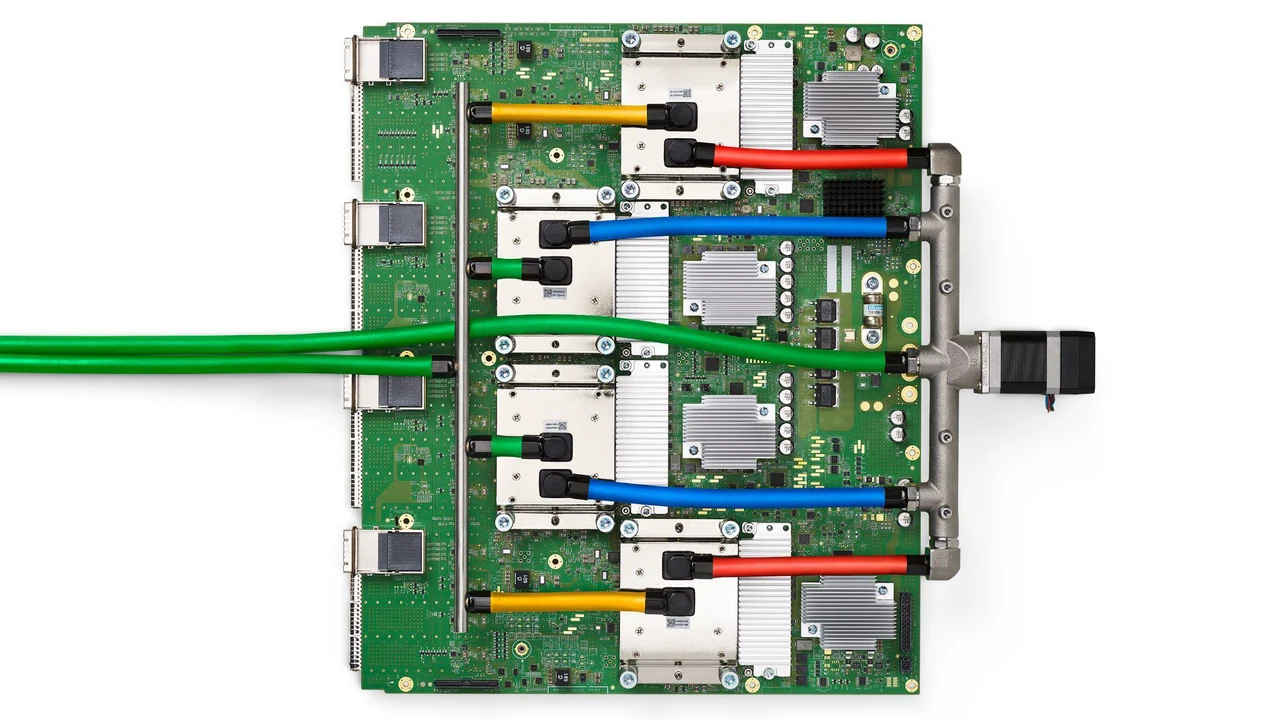
Photo credits

Google has added two specialized systems to its eighth-generation Tensor Processing Unit (TPU) lineup to support secure artificial intelligence computing and workloads that require massive memory capacity. The expansion brings the company's total number of eighth-generation configurations to four, reflecting the growing demands of enterprise artificial intelligence infrastructure.
The new systems, named TPU 8tx and TPU 8i Max, are designed to address challenges that emerge as businesses deploy autonomous software agents. One system prioritizes confidential computing for sensitive workloads, while the other targets models that handle enormous amounts of contextual information. Google's accelerator business currently serves nearly 100 customers, including research laboratories, financial trading firms, retailers, and universities.
Security and Isolation in TPU 8tx
TPU 8tx is built for organizations that process sensitive information or must follow strict regulatory rules. Google integrated hardware-level confidential computing into the system to protect data and model weights while they are actively being processed. Traditional processors usually must decrypt information before working with it, which creates potential exposure even when storage and network connections use encryption.
To solve this vulnerability, TPU 8tx uses hardware-based isolation that pairs the processor silicon with fifth-generation AMD EPYC CPU hosts and low-latency Boardfly networking technology. According to Google, this setup cuts latency by up to half compared to the standard TPU 8t model while keeping security performance penalties minimal. Organizations can use the system to fine-tune proprietary models using private datasets and distill larger models into smaller versions without transferring sensitive information between separate computing clusters.
Managing Memory and Software Deployment
TPU 8i Max addresses a different limitation related to memory bandwidth. Large artificial intelligence workloads increasingly require processors to access enormous amounts of information quickly without waiting for data transfers. Google combines two TPU chips within a single package to double compute capacity, on-chip SRAM, and high-bandwidth memory performance, fitting twice the hardware within the same physical rack space.
Hardware improvements are paired with software updates designed to reduce the expertise required to deploy workloads. An open-source project called TorchTPU brings native support for popular PyTorch code and Hugging Face models so developers can run existing applications without rewriting them. Google also introduced a preview agent suite compatible with Claude Code, Cursor, and Google Antigravity to automate onboarding, identify performance bottlenecks, and optimize custom kernels. Another addition, TPU Sync, creates a unified memory architecture across TPU memory, host memory, and shared storage that can reduce key-value cache transfer latency and time to first token by more than 90 percent.
Summary
As autonomous agents handle increasingly complex tasks, businesses need artificial intelligence infrastructure that evolves beyond faster individual processors to prioritize memory, networking, and security.
Updates and corrections
- Update, : Linked every claim to Google’s original November 9 system announcement and clarified that the TPU agent suite is in preview. Performance claims come from Google.